A lot of agent setups call a large language model for everything. The model writes the reply, and it also decides which tool to call, whether a command is safe, which skill to load and whether a test run passed. Only the first of those jobs needs text. The rest are choices from a short list, and asking a text generator to make them means paying for a paragraph when you wanted one word. Below I explain what a decision model is and the architecture that keeps showing up wherever one is used well. Then I go through the places it already runs and show you how to find the decisions hiding in your own workflow.
What a decision model returns
A generative LLM returns a string. You ask it "is this command safe to run?" and it answers with a sentence, which your code then has to parse, hope it parsed correctly, and turn into a yes or a no.
A decision model skips the sentence. It returns a typed output: one option picked from a set you defined, a true/false flag, or a score, along with a probability or confidence for each. Your software can act on that directly. There is nothing to parse, and the confidence number tells you when the answer is shaky enough to hand to a person.
The clearest example I know of is Jev, built by TypeSafe AI. Jev doesn't generate language at all. It is built only to return fast, structured decisions. TypeSafe claims it matches frontier LLMs on structured decision-making tasks while running 40 to 200 times faster and at substantially lower cost. I haven't run Jev myself, so I treat that claim, and every other number in this article, as the claim of whoever measured it. The architecture is what I want you to take away, whatever the benchmarks end up showing.
The pattern: code, decision model, LLM
Look at enough systems built this way and the same split appears every time. Each layer does the one thing it is good at.
- Code does anything that must be exact: math, physics, timing, parsing, safety limits.
- Code also prepares a bounded list of legal options and attaches the facts needed to choose between them.
- The decision model picks among those options and says how sure it is.
- A generative LLM is called only when text really has to be written.
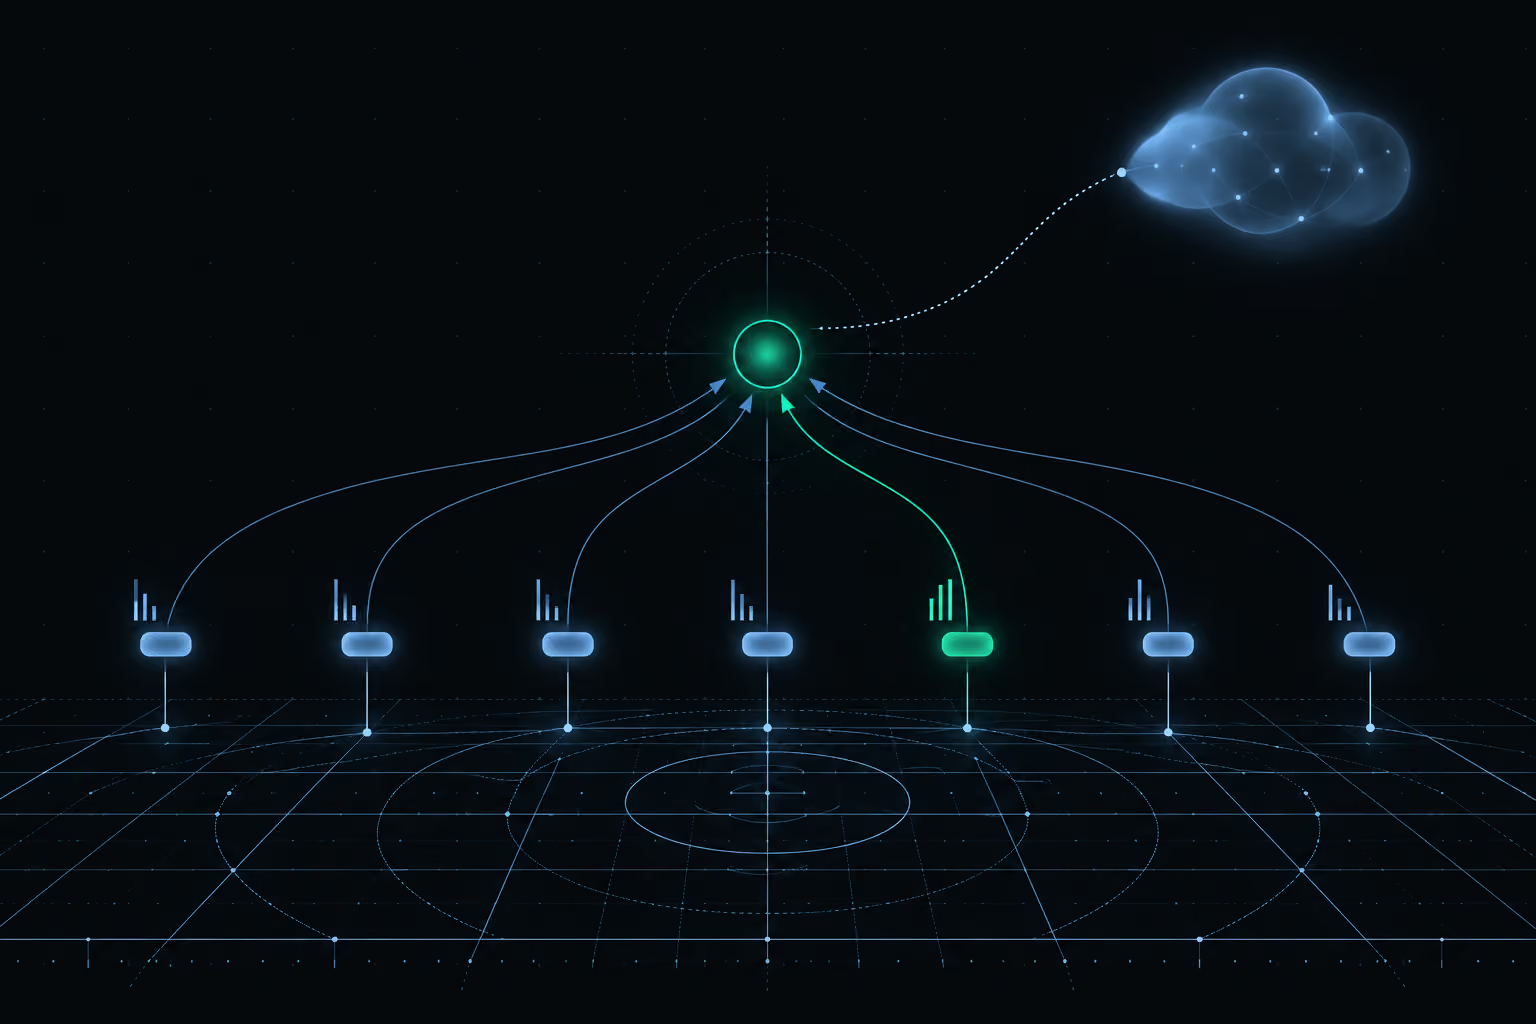
The second point is the one people skip. The decision model never invents an action. Code hands it a menu, and it can only order from that menu. That constraint is what makes the output safe to act on.
A browser agent from Browser Use shows the split cleanly. Instead of sending screenshots to a large model, it turns the current page into an indexed table of visible elements. Jev then picks both the operation (click, type, select, scroll, wait or finish) and its target in a single request. A smaller LLM steps in only when the agent has to produce text, for example a city name for a search field. Code prepares the page, the decision model picks, and the LLM only writes the city name.
Where the pattern already runs
The projects below fall into six groups by the kind of decision they make.
Routing and choosing what to load
Cloudflare has added Jev to its AI platform as a model for routing requests, selecting tools and making other choices that sit on an application's critical path. One agent task can trigger many model calls and latency adds up with each one, so a slow router slows every step after it.
Two community projects apply the same idea to what an agent reads. The Jev Capability Resolver stores documented operations in a tree of providers, resources and individual commands. Jev walks the tree one level at a time, picks the most relevant branch at each level, and returns only the documentation attached to the final operation. The large catalogue stays out of the agent's context.
A Claude Code mod does the same for skills. Normally the full skill list is exposed to the model, which adds context even when most skills are irrelevant. The mod hides that list and sends the skill names and descriptions to Jev instead. Jev first decides whether the request needs a skill at all, then ranks the candidates and double-checks the top ones. Only the chosen skill's SKILL.md goes into Claude's context.
Compaction: score, don't summarise
When a long coding session fills the context window, the usual move is to ask an LLM to summarise the older part. Summaries lose details, and in code the details are the point: an exact file path, a command, an error message, a constraint someone stated an hour ago.
fast-jev-compaction, a Claude Code plugin and npm library, treats compaction as a decision instead. It sends the conversation state to Jev, which scores each tool call and its result on whether it is still needed. Unneeded calls and results are removed. Useful ones stay verbatim. Less important results can be truncated while the tool call itself is kept. User and assistant messages stay in their original form and order. Because nothing is rewritten, nothing can be paraphrased wrong.
Evaluation
LangChain researchers tested Jev as a judge for AI agents, as an alternative to LLM-as-a-judge. They ran a weather agent on five fixed tasks and scored the same runs repeatedly with Jev and with several LLMs, using human reviewers as the reference. In that experiment Jev matched the human pass/fail call in all 500 repeated decisions, and its scores varied far less from run to run than the LLMs' did. If that holds up, scoring far more production traces and running regression checks more often becomes practical.
The researchers added their own caveat, and I think it matters more than the result. The experiment was narrow, and consistency alone does not guarantee correctness. A judge that gives the same wrong answer every time is perfectly consistent. Only a comparison with humans on your own cases tells you it is right.
Safety review of agent commands
Vercel uses Jev as the safety reviewer in fx, its coding agent. In fx's auto mode, every command the agent proposes is checked before it runs. Vercel says its internal benchmark found Jev roughly 5 to 18 times faster at p95 than the LLM reviewer it already used, with more accurate safety classifications.
This is the textbook case. "Can this command run?" has a bounded answer and sits directly on the critical path: the agent waits for the verdict before every single action. Vercel has since made Jev available through its AI Gateway for guardrails, routing and other typed decisions.
Bulk classification with a human spot-check
DAIR.AI had around 2,300 AI research papers in its Academy collection, tagged earlier with a generative model, and those tags weren't trusted enough to use without further checking. Instead of building and tuning a more expensive few-shot LLM classifier, they ran the collection through Jev. It agreed with about three quarters of the existing tags and proposed roughly 579 high-confidence topic changes. A person then reviewed 30 of the disagreements by hand, accepted all of them, and only then were the changes applied to the production collection.
Two things are worth copying: a generative model handled the broader processing while the decision model did the classification at scale, and a human checked a sample before anything shipped. Thirty cases is a small check, but it is a real one.
Real-time control
In TypeSafe Mario, code reads the emulator's telemetry and memory and turns it into structured JSON: Mario's position, velocity and jump trajectory, nearby enemies, terrain, reaction timing and recent actions. Jev chooses from a small set of legal controller actions, such as moving right, running, jumping or doing nothing. Each request also returns a true/false call on whether a forward jump is useful and a score for immediate danger. The emulator advances a few frames before the next decision, and precise timing stays in code.
JevBall is a 3D football match with all 22 players controlled by Jev. For each player, the simulation first computes the realistic options locally (pass, shoot, dribble, press, mark) and attaches facts such as distance, lane clearance, receiver space, estimated success, expected goals and offside margin. Jev chooses among up to 14 typed options per player and returns a probability for each one. The ball carrier decides more often than players far from the ball, and decisions due at the same moment go out in one batched request. Physics, first touches and goalkeeper saves stay in code.
Jev Autopilot flies a drone through a randomly generated city in a Three.js simulator. Jev gets a compact situation report (altitude, speed, bearing, nearby obstacles, the tallest building on the route) and makes six decisions per request: throttle, yaw, pitch, roll, whether to commit to landing, and whether to cut the motors. The simulator turns the probabilities into stick movements, while code handles the flight calculations and basic safety limits.
None of these projects uses a vision pipeline or asks for natural-language instructions. The world is described as data, the decision model chooses, and code executes.
How to spot a decision in your own workflow
You don't need Jev to use this pattern, only the habit of noticing when a step is actually a decision. Walk through your workflow and ask three questions of each step.
- Is the answer set bounded? Could you write every acceptable answer on a card before the step runs: yes or no, one of these seven tools, one of these twelve tags, one of these legal moves? If the answer is free text, it isn't a decision.
- Is it on the critical path? Does the rest of the work wait for this answer? Routing, tool choice and safety checks usually block everything after them.
- Does it repeat many times? Once per command, per page, per document, per frame? A choice made once a day doesn't need optimising; one made on every request does.
When a step says yes to all three, you have a strong candidate. Typical ones: which tool or skill to use, whether a proposed action is allowed, whether an agent run passed, which category an item belongs to, which part of the context is still needed.
Before you swap anything, check that code can build the option list. If it can't, the decision model has nothing to choose from, and you're looking at a generation problem.
When not to use a decision model
Here are the situations where I'd keep an LLM or plain code instead.
- The output has to be written text: a reply, an email, a summary a person will read.
- The option set is open-ended or changes on every request in ways code can't list ahead of time.
- The step runs rarely and isn't blocking anything. The speed and cost gain is real only at volume.
- A deterministic rule already does the job. If a regular expression or a lookup table gets it right every time, no model belongs there.
- You have no way to check the answers. Without your own evaluation set and some human comparison, a confident, consistent decision model can be confidently and consistently wrong.
The principle to keep
The rule I take from all of this: give each step the cheapest thing that can do it correctly. Exact work goes to code, choosing from a known list goes to a decision model, and writing goes to an LLM. Using an LLM is fine. Asking it to do the math and the choosing as well, just because it can, is where the time and money leak out.
If you want a first step, take the agent you rely on most, list every model call it makes, and mark each one "writes text" or "picks from a list." The calls in the second group are where you'll find your first decision.