An announcement lands: a new "model" matches the strongest models on the market on selected benchmarks. Within a day, everyone wants to try it. Before you move your work onto it, it helps to know what you are actually buying. Quite often it is not a smarter model at all. It is a manager that splits your task across models you already know. I will show you how that setup works, how to test it fairly, and when it has a real chance of paying for itself.
A small fish that hands out the work
The clearest example is Fugu and Fugu Ultra from Sakana AI, a Japanese company. "Sakana" means fish in Japanese, and the logo shows a school of small fish forming one large one. It is a good picture of the whole idea.
From the outside you see a single API: one access point your program sends a request to and gets an answer back from. Behind it sits a small manager model trained for one job: break the task into parts and pass them to frontier models from different vendors, such as Claude, GPT and Gemini. Claude might get the writing, GPT the code and bug fixes, Gemini the fact-finding. Harder tasks can pull more models into the pool.
The vendor describes it as a multi-agent system delivered as one model. That is a fair description, as long as you read it carefully. Fugu is not a new large language model that outperforms the rest. The vendor's claim is this: by combining existing models, it reached results on par with the strongest available models, such as Fable and Mythos, on certain benchmarks. That is a claim, not a verdict, and I suggest you treat it that way until you have checked it against your own work.
You already know this pattern from sub-agents
An orchestrator, meaning a program that coordinates several models, is not a new idea. If you work in Claude Code, you see the pattern every day: the main agent breaks down a plan, hands parts to sub-agents running cheaper or stronger models, and assembles the result. Fugu changes one thing. Instead of coordinating models from a single vendor, it coordinates across vendors, and a trained model makes the split instead of you.
Every orchestration comes down to two questions. First: who does which part? You have a job made of steps A, B and C, so one model takes A, another takes B, and so on. Second: who puts it together? Once the individual models return their pieces, you still need one more model to merge them into a single answer.
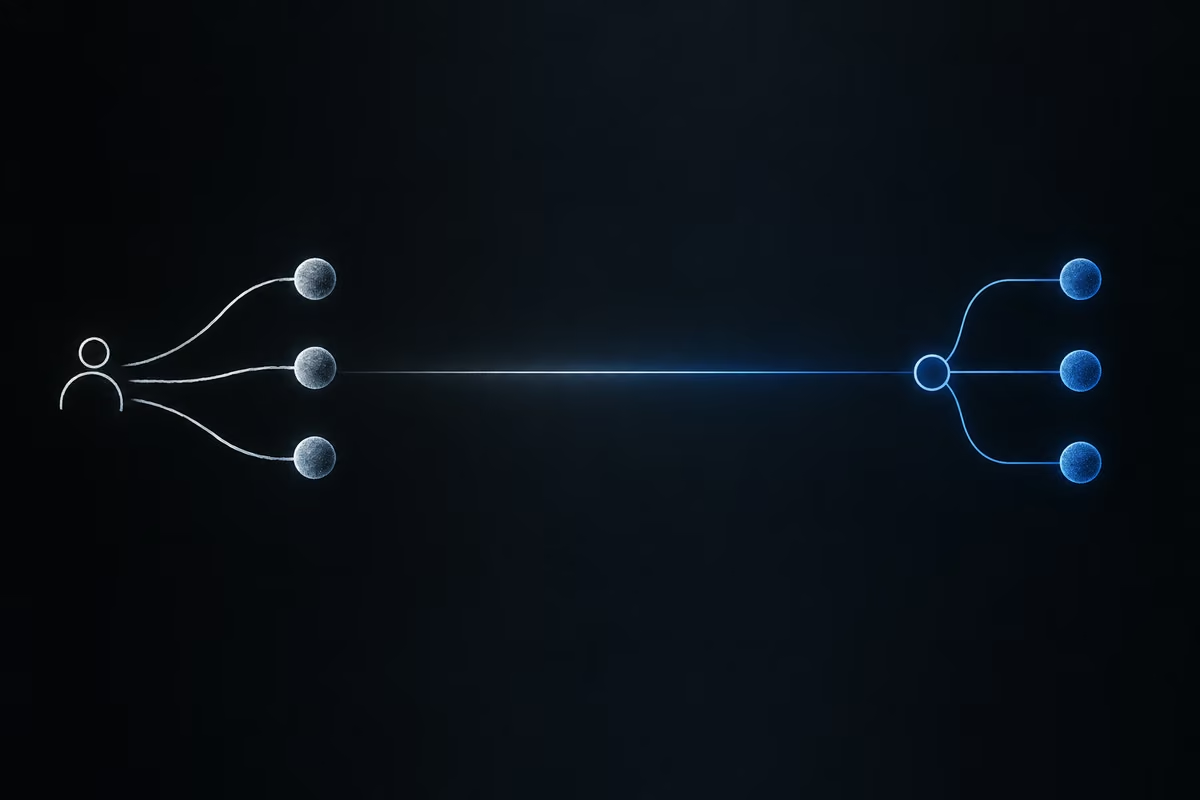
It helps to picture a scale. At one end, you write everything and decide which model does what yourself, say by planning in one tool and sending code for review to another. At the other end, a model makes those calls automatically. An orchestrator behind one API moves you to that far end. It adds no new capability. It takes the manual routing off your plate.
Keep this apart from a different pattern that travels under similar labels. You can also send the same prompt to three models in parallel and ask a fourth to act as a judge and merge the best answer. That is how OpenRouter's Fusion API works, for example. Nobody splits the task there; every model answers the whole thing. Both approaches can lift quality, because different models bring different perspectives. Both pay for it the same way: with time and money.
How to test the claim fairly
A vendor's score on selected benchmarks tells you nothing about your tasks. To learn anything, a comparison has to meet a few conditions.
Same prompts and same inputs for both sides. Tasks with an objective pass/fail result, not a one-to-ten scale where the score drifts into taste. A varied set: puzzles, trap questions, work against a spec, heavier algorithms. A grader independent of both systems, ideally one that also wrote the tasks, so neither side sets its own exam. And above all, measure three things, not one: quality, time and cost.
That last part is the one people skip. A quality-only comparison always looks harmless, because an orchestrator that draws on the best models will rarely come out worse. The real question is what the same result costs.
What a 38-task comparison showed
In a comparison across 38 tasks, Fugu Ultra was set against a single model, Claude Opus 4.8. The tasks ran in four waves (puzzles, traps, specs, heavier algorithms), both systems got identical prompts, and a separate tool, Codex, independent of both sides, wrote and graded the tasks. Billing went through the API, meaning you pay for actual usage.
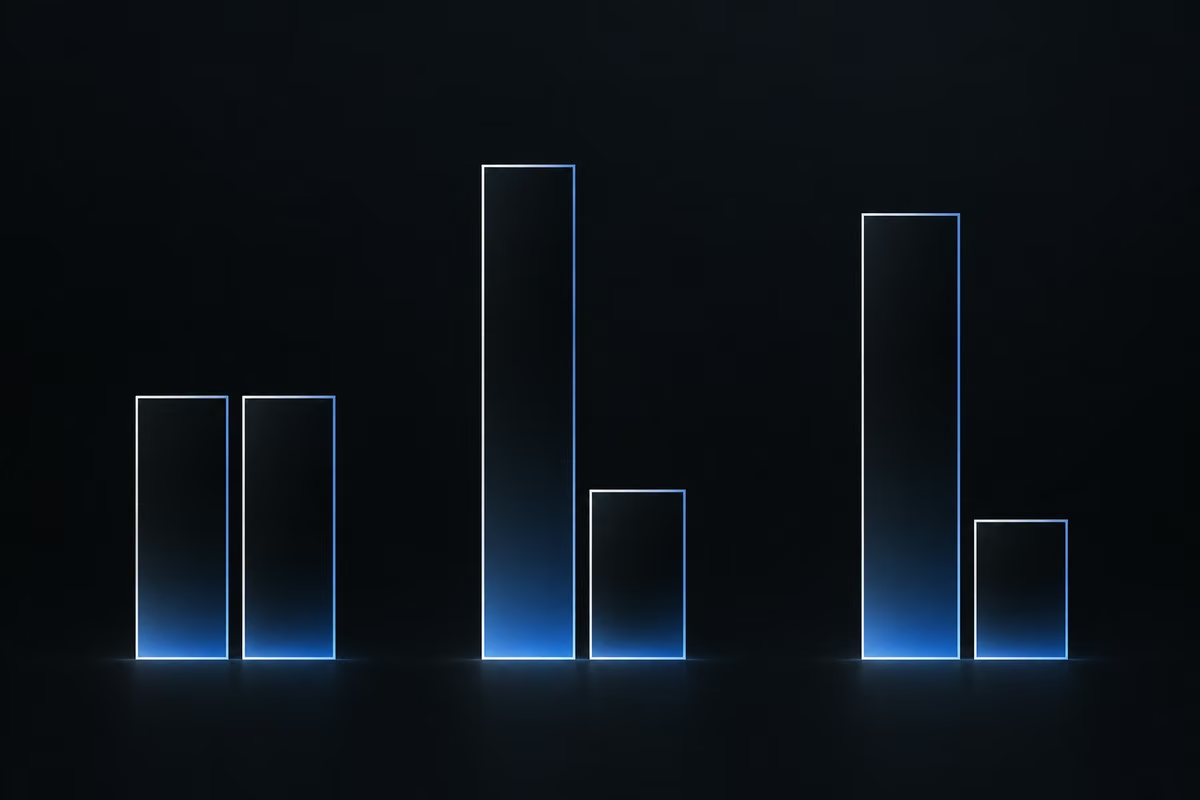
Quality: 36 of the 38 tasks ended in a tie. The single model won the remaining two. The orchestrator won none.
Time: about 357 minutes in total for the orchestrator against about 80 minutes for the single model, roughly 4.5 times longer. The gap shows most on easy tasks. Where the single model answered in a few seconds, the orchestrator needed several minutes, because even a trivial prompt goes through splitting, delegating and merging.
Cost: around $50 for the orchestrator's full run against around $10 for the single model, roughly five times more. You pay for several models at once and for longer runs.
One caveat changes how you read this. Opus 4.8 is one of the models in the pool the orchestrator picks from. Part of the comparison was a model against itself wrapped in a management layer, so a tie is no surprise. A second caveat is scope: these were tasks written by a model, not weeks of refactoring a large codebase. For that kind of work, this test gives no answer.
Integration and limits: what the announcement leaves out
The orchestrator could be connected to an agent harness, the program in which a model reads files, runs tools and carries a task through to the end. In everyday knowledge work, with research and custom skills, it behaved correctly, just slowly. Connecting it is not a simple swap of endpoint and API key, as it is with many other models. It needs its own setup, and some things behave differently: the context-usage counter, for instance, could sit at zero for many rounds of conversation, because the answers come back from the orchestrator's server.
The second issue is limits. Access comes as a subscription or as pay-as-you-go billing. The rolling usage windows on the subscription filled up very fast, clearly faster than a typical agent-harness subscription, even on a higher plan. That follows naturally when every prompt runs several models at once.
Where this setup might pay off
I am not saying cross-vendor orchestration is a dead end. There is a specific profile of work where it may earn its cost: heavy software engineering, where you want one vendor's model to plan and another vendor's model to review, without wiring that up by hand. The same goes for teams where many people work on one codebase and already run two tools side by side. If you switch between them anyway, one API can take some of that work off you.
For knowledge work, such as writing, research or analysis, the test gave no reason to pay more and wait longer for the same quality.
The lesson that outlasts any one tool
I think the direction is right. Don't lock yourself into one provider. Learn your unit economics, meaning what one run of a given task costs you, and look for the cheapest model that does not lower the quality of that task. As models get more expensive and the strongest ones are sometimes unavailable, that skill matters more. The point is to do it deliberately and with data, rather than handing it wholesale to a layer whose decisions you cannot see.
And before you switch to anything announced as matching the best, test it on your own work: the same tasks, objective criteria, an independent grader, and time and cost next to quality.
My rule is simple: a management layer adds no quality beyond what its workers can already deliver. You pay for coordination in time and money, so it has to deliver something you can measure on your own tasks. Next time a new tool makes that promise, start with ten tasks you know by heart and measure all three.